StartHub - Boosting Throughput 10x by Making the LLM Service Non-Blocking
Overview
Tackling rising request latency and failure rates under increasing traffic
Tech Stack

Kotlin

Spring Boot

FastAPI

MySQL

Redis

Docker Compose

GCP

GitHub Actions
Team
7 members (2 Backend & AI, 3 Web, 2 App)
Period
2025.04 ~ 2026.04
Details
Overview
- StartHub is an AI startup support platform that addresses the challenges founders face by building a RAG system from scratch to support the entire pre-launch journey, with features such as tailored support program recommendations, an AI chatbot based on user activity, business model canvas generation, and competitor analysis.
- Korean startups have a survival rate of 33.8%, below the OECD average of 45.4%, and about 90% fail due to factors such as insufficient funding (38%), lack of marketability (35%), and flawed business models (20%). The project began from this problem.
- Features requiring real-time web search, such as competitor analysis, were handled by integrating the Perplexity API.
Problem — Increased Request Latency & Failure Rate in the LLM-Based Service Under Rising Traffic
- The LLM-based features were being processed with a blocking, thread-pool-based architecture.
- During the long response delays of the Perplexity API, threads were left waiting on I/O.
- As traffic increased, the thread pool expanded and memory usage grew linearly.
- We were failing to leverage WebFlux's key strength of high-concurrency, non-blocking processing.
Solution 1 — Migrating Thread-Based Async to Kotlin Coroutines
- Replaced Spring @Async and CompletableFuture with CoroutineScope and Deferred.
- Built an asynchronous processing architecture integrated with WebFlux via kotlinx-coroutines-reactor.
Solution 2 — Converting Blocking I/O to Non-Blocking
- Converted .block() on Perplexity API calls to .awaitSingle().
- Converted CompletableFuture.get() in duplicate-request handling to Deferred.await(), so that threads yield while waiting on I/O.
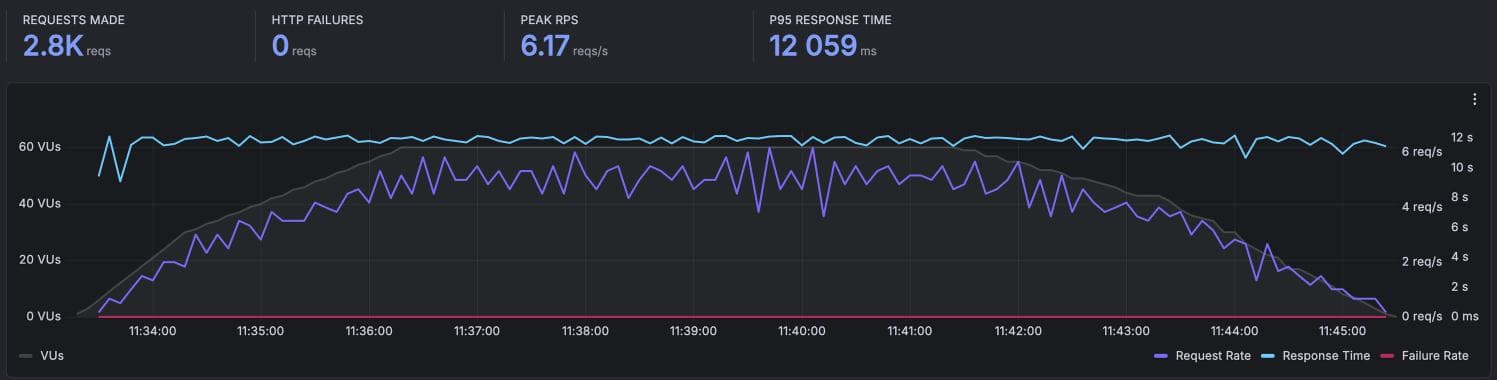
Results — Over 10x Higher Concurrent Throughput and ~90% Lower Memory Usage
- Built a Grafana monitoring server, then ran and analyzed K6-based load tests.
- Achieved end-to-end non-blocking, improving concurrent throughput more than 10x and reducing memory usage by roughly 90% with the same resources.
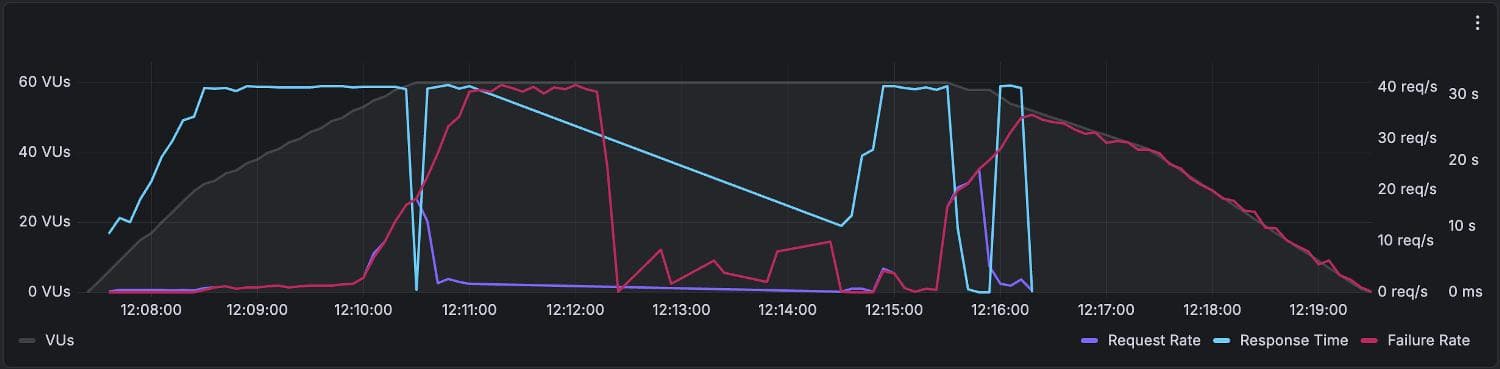
- Dramatically improved the issue where requests failed under overload once virtual users (VUs) reached the threshold.
Before Introducing Non-Blocking
- Once VUs reached the threshold, the failure rate spiked and caused service outages.
After Introducing Non-Blocking
- Concurrent throughput rose significantly and achieved zero HTTP failures.